app.virtconsole.com/kubernetes/clusters/prod/pools
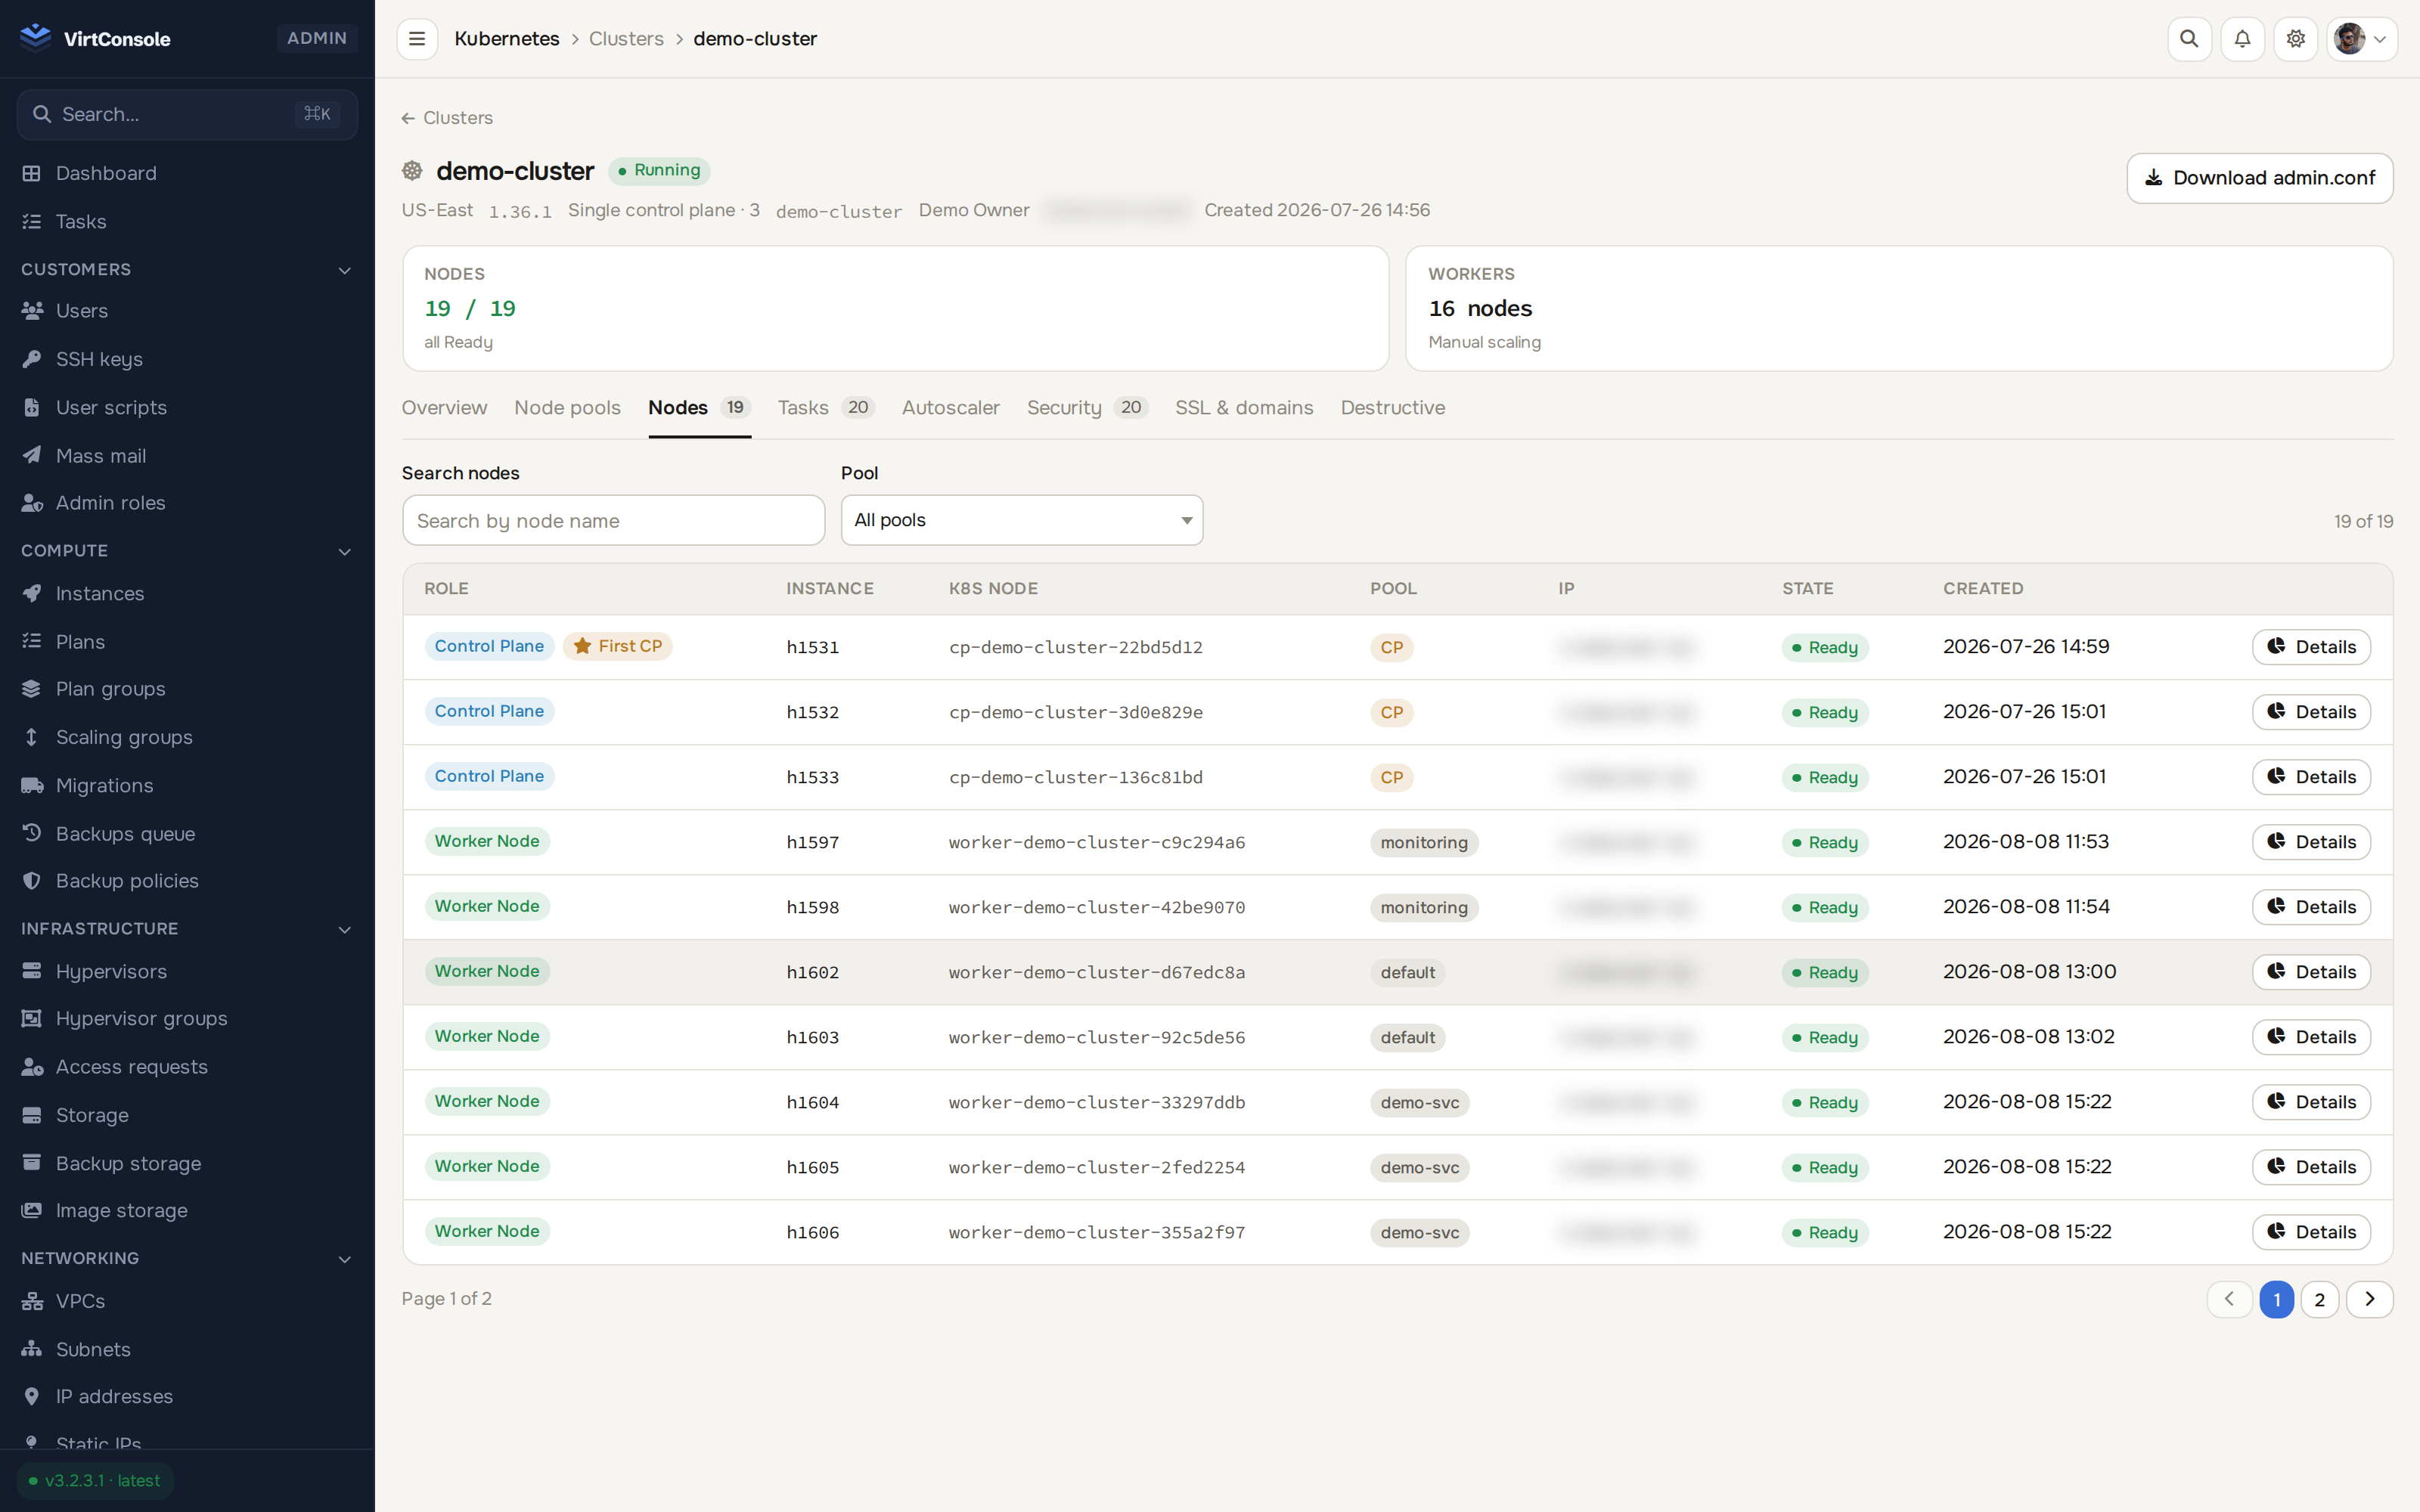
The standard upstream cluster autoscaler, wired to your hardware. Workers scale up when pods are pending, down when nodes are underutilised, inside bounds that are enforced strictly.
A real autoscaler, not a cron script.
When pods cannot schedule, workers are added to the pool that can host them, and appear in the LB pool within seconds.
Underutilised nodes drain gracefully and leave, respecting PodDisruptionBudgets and scale-down ordering.
Min and max per pool are enforced at the platform level, so costs never run away overnight.
Autoscaling composes with everything else.
Each pool scales independently. Keep a general pool warm while a GPU pool sleeps at zero.
Type a number and hit Scale at any time. In-flight pods keep running while the pool adjusts.
Scale-down ordering survives plan rotations, so the pool never scrambles which node leaves next.
The unglamorous parts are handled.
The in-cluster autoscaler token rotates automatically 30 days before expiry, with a heads-up email.
Headroom is measured against each node’s effective memory ceiling, so a sanctioned overcommit node counts its real capacity and an over-allocated one sorts last.
Upstream cluster autoscaler plus metrics-server, so kubectl top and HPA behave exactly as documented.
Pool min/max, control plane status and worker inventory sit side by side on the same screen the autoscaler reports back to.
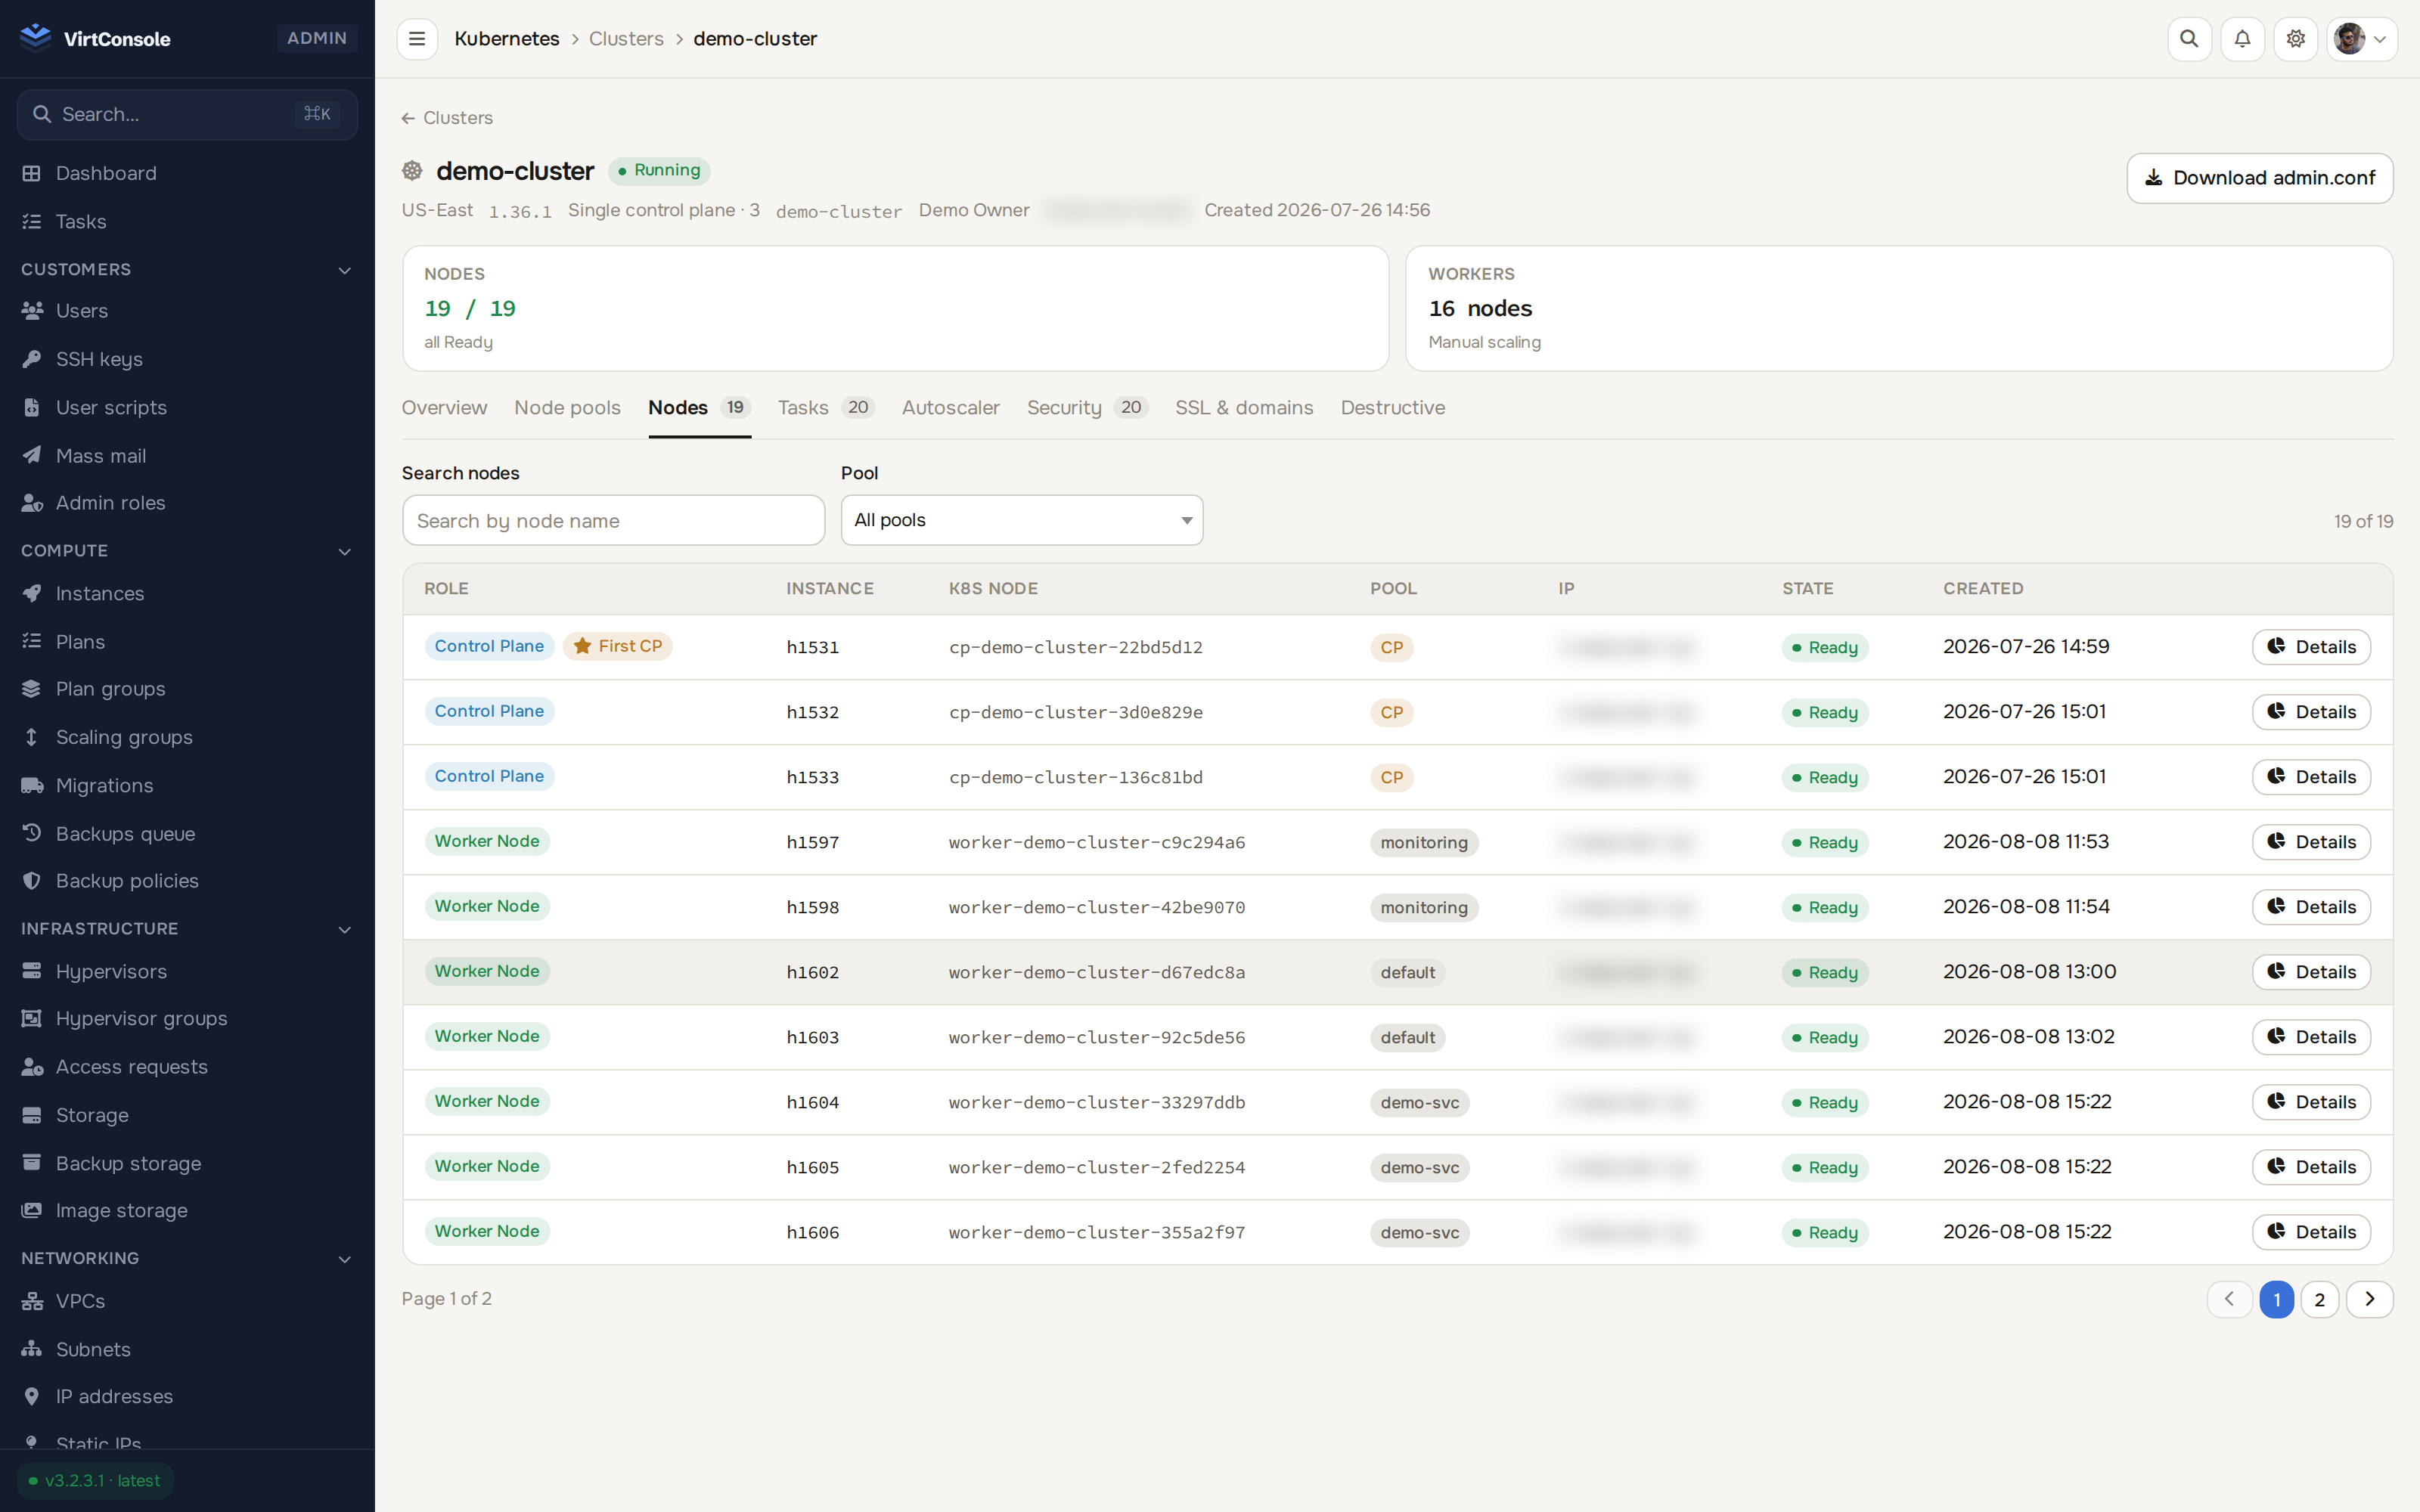
The full cluster page the autoscaler works against
Free 30-day trial. Every feature included. No credit card required.
30 days, every feature, no credit card, VirtConsole installs with the trial active by default. Just run the installer on your own hardware.
Debian 11/12/13 · Ubuntu 22.04/24.04/26.04 · Rocky / Alma / CentOS Stream 9/10 · run as root.